Indexed Though Blocked by Robots.txt: Fix It is useful when it helps a real reader or operator make a better decision, not when it adds another isolated SEO tactic. For arjns-style publishing, the page should explain the problem, show the practical workflow, name the risks, and give a repeatable way to review the result. Robots.txt controls crawling, not indexing. First decide whether the URL should be searchable, excluded from search, redirected, removed, or private; then apply a signal Google can actually access and verify.
Why a blocked URL can remain indexed
A robots.txt disallow rule stops a compliant crawler from fetching the URL; it does not order a search engine to remove a URL already known through links, sitemaps, redirects, or earlier crawls. Because the blocked response cannot be fetched, a noindex directive placed on that response may also remain unseen. The durable fix begins with the intended outcome: allow crawling for an indexable page, allow crawling long enough to read noindex for a public page that should disappear, redirect a moved resource, return 404 or 410 for a genuinely removed resource, or require authentication for private material.
Evidence to capture before changing robots.txt
Treat the warning as a state to classify, not a command to unblock every URL. Preserve enough evidence to explain both the current state and the chosen destination state.
- Record the production response, rendered robots meta, canonical, sitemap membership, internal links, and the exact matching robots rule for representative URLs.
- Separate URL discovery from response processing so an indexed URL-only result is not mistaken for crawled content.
- Set a review date based on observed recrawl evidence, then confirm the reported canonical and index state rather than repeatedly requesting indexing.
Diagnose the robots and index state
Start by separating the user need from the search engine signal. The user need is what the page must solve. The search signal is how crawlers and ranking systems understand that solution. If the page only chases the signal, it becomes thin. If it only helps the reader but hides the structure, it can be harder to discover. The right answer is a clear page with crawlable HTML, precise metadata, useful examples, internal links, and a measurable follow-up.
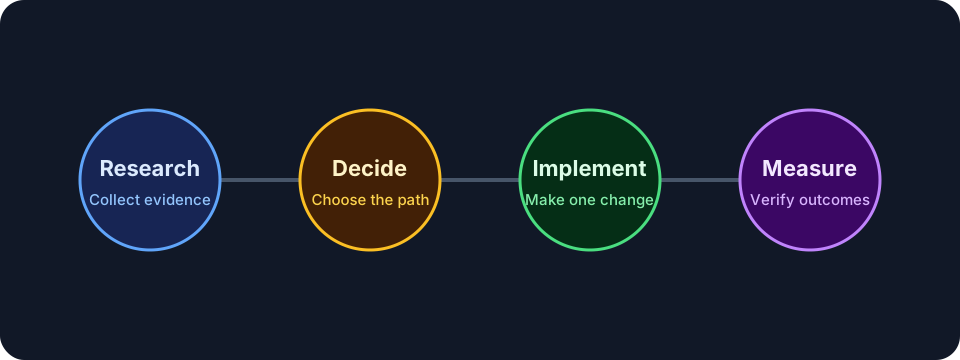
Choose the correct removal or access path
- Export affected URLs from the Page indexing report and group them by template, directory, parameters, and intended purpose.
- Inspect representative URLs and record indexed status, last crawl, canonical, referring sitemap, and live-test result.
- Test the exact URL against user-agent groups, wildcard rules, case, host, protocol, and trailing-slash variants in robots.txt.
- Choose one outcome for each group: crawl and index, crawl but noindex, redirect or retire, or protect with authentication.
- For indexable pages, remove accidental blocks, return 200, use a consistent canonical, retain useful links, and list only canonical URLs in sitemaps.
- For public non-indexable pages, allow crawling, add noindex, remove them from sitemaps, and reduce unnecessary discovery links.
- Use a permanent redirect, 404 or 410, or authentication for moved, deleted, or private content instead of treating robots.txt as access control.
- Re-test production behavior and monitor until Google recrawls the URL and reports the intended state.
- Document the expected search intent, the page promise, and the verification method before publishing.
- Review the rendered page on mobile because cramped layouts, hidden tables, or broken controls can turn good content into a poor experience.
Decision matrix for a blocked URL
Use this decision matrix: public and searchable = allow crawl, return 200, stay indexable, and include the canonical URL in the sitemap; public but absent from search = allow crawl, return 200 with noindex, and exclude it from the sitemap; permanently moved = allow crawl and return 301/308 to the final URL; gone = return 404/410; confidential = require authentication and never expose it publicly.
- Write the page brief before writing the final article.
- Name the primary query group and the reader's next action.
- Check the rendered page, not only the draft data.
- Record the verification date so later reporting has context.
Robots and indexing verification checklist
- The title, H1, summary, and first section describe the same practical outcome.
- The page includes examples or decision rules a reader can apply immediately.
- Important links are crawlable anchors with natural context.
- The sitemap includes the page only when it is live and canonical.
- The page avoids claims that cannot be verified from visible content or data.
- The review date, publish date, and next measurement point are clear to the editor.
Signals Google must be able to fetch
Use decision rules to keep the work honest. A rule prevents the page from becoming a collection of SEO opinions and makes the review easier for another person. The rule should explain what to do when evidence is weak, when a page is too thin, when a signal conflicts with another signal, and when the safest answer is to wait for better data.
- If the page cannot answer a clear reader need, do not publish it as indexable content.
- If the technical signal conflicts with visible content, fix the visible content or remove the signal.
- If a section only repeats the title in different words, replace it with an example, checklist, or caveat.
- If a change cannot be verified, mark it as an editorial assumption rather than a completed fix.
- If a future page is scheduled, keep it out of public links and sitemaps until the publish date.
When robots.txt is not the removal tool
Do not use robots.txt to protect customer records, staging environments, invoices, account pages, or any confidential file: blocked URLs can still be discovered and the server may still serve them to anyone. Require authentication or network access controls. Do not unblock an infinite faceted or parameter space merely to expose noindex without first controlling crawl paths and generation. For an urgent temporary search hide, a removal request can complement the underlying fix, but it does not replace it.
Robots.txt fixes that preserve the problem
- Adding noindex while robots.txt still prevents Googlebot from reading it.
- Using robots.txt as a privacy or security control.
- Blocking CSS or JavaScript that Google needs to understand the page.
- Validating the fix before the production rule has actually changed.
- Removing discovery links before understanding why the URL is indexed.
Confirm recrawl and index-state change
Measure this work with a short feedback loop: crawl status, sitemap visibility, impressions for the intended query group, clicks and CTR when snippets change, engagement on the page, and whether the reader continues to a related guide or tool. Do not judge success from a single day of data; search systems, crawling, and reporting all move on different timelines.
Robots and indexing verification checklist: release checks
- Confirm the canonical URL, title, meta description, headings, and language alternates.
- Open the page on mobile and desktop to check spacing, tables, diagrams, and code blocks.
- Verify the page appears in the sitemap only when it is live.
- Check that images have useful alt text and do not create layout shift.
- Add internal links from related guides after the destination page is public.
Recommendation: match the control to the outcome: AI review prompt
Use this prompt after you have a real URL, page draft, or crawl export. It is meant to produce fixes you can review, not automatic publishing decisions.
Act as a careful SEO implementation reviewer.
Page/topic: Indexed Though Blocked by Robots.txt: Fix It
URL or draft: [paste URL or content]
Search intent: [intent]
Review: crawlability, title, meta description, headings, content depth, examples, internal links, structured data/canonical needs, mobile UX, and measurement plan.
Return prioritized fixes with exact page sections to change.
Frequently asked questions
Can robots.txt prevent indexing?
No. It prevents compliant crawlers from fetching a URL, but a discovered URL can still be indexed.
Should I add noindex to a blocked page?
Not while it is blocked. Googlebot must crawl the response before it can see noindex.
Is this warning always harmful?
No. Decide whether the URL should appear in search before treating the status as an error.
Does temporary removal solve it permanently?
No. Correct the underlying crawl, index, redirect, deletion, or access rule.
Recommendation: match the control to the outcome
A strong SEO page is not only optimized for a keyword. It is reachable, understandable, useful, and honest about what it can answer. Before publishing, check the rendered page, the snippet fields, internal links, indexability, and whether a reader can act without opening five more tabs.
Revisit the page when search intent changes, when the product or platform changes, when Search Console shows new query groups, or when users repeatedly need clarification. Refreshing content should make the page more accurate and useful; it should not be a cosmetic date change.