Robots.txt is a plain text file at the site root that tells crawlers which URL paths they may request. It is useful for managing crawler traffic and keeping low-value paths from being fetched too often. It is not a privacy control, and it is not the right way to remove an HTML page from search results.
What this page must do
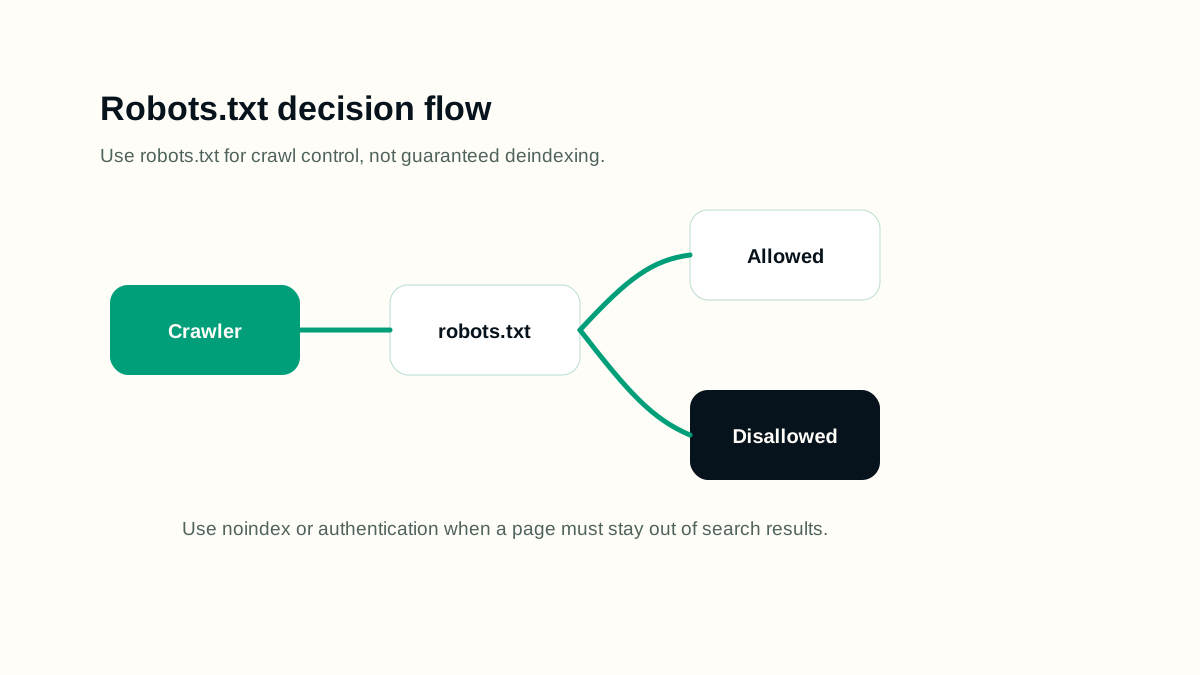
Use robots.txt for crawl control, not indexing control. If a page must not appear in search, use noindex or authentication while allowing the crawler to see the noindex directive. If robots.txt blocks a page, a crawler may never see the page-level directive. Keep the file simple, add a sitemap reference, and test the exact paths you care about.
A practical workflow
- List paths that should be crawled and paths that should not be fetched frequently.
- Keep public CSS, JavaScript, images, and article pages crawlable.
- Use Disallow for low-value crawl paths such as internal search, admin, cart, or duplicate parameter areas when appropriate.
- Use noindex or authentication for pages that must stay out of search results.
- Add the canonical sitemap URL.
- Test important URLs after every robots.txt change.
Working example
Imagine the page is being prepared for a real publishing queue. The editor has one URL, one primary intent, a sitemap rule, and a follow-up date. For robots.txt guide for seo, the useful work is to decide what must be visible before launch, what can be measured after launch, and which signals would prove that the page is helping users instead of only adding another URL.
- Write the page brief before writing the final article.
- Name the primary query group and the reader's next action.
- Check the rendered page, not only the draft data.
- Record the verification date so later reporting has context.
Implementation checklist
- The file is available at /robots.txt and returns 200 text/plain.
- Important pages and assets are not accidentally blocked.
- Disallow rules match path prefixes exactly as intended.
- The sitemap URL uses the preferred canonical host.
- No private URLs are revealed unnecessarily through comments or sitemap references.
- A robots rule is not being used where noindex or authentication is required.
Decision rules
Use decision rules to keep the work honest. A rule prevents the page from becoming a collection of SEO opinions and makes the review easier for another person. The rule should explain what to do when evidence is weak, when a page is too thin, when a signal conflicts with another signal, and when the safest answer is to wait for better data.
- If the page cannot answer a clear reader need, do not publish it as indexable content.
- If the technical signal conflicts with visible content, fix the visible content or remove the signal.
- If a section only repeats the title in different words, replace it with an example, checklist, or caveat.
- If a change cannot be verified, mark it as an editorial assumption rather than a completed fix.
- If a future page is scheduled, keep it out of public links and sitemaps until the publish date.
Common mistakes
- Blocking a page in robots.txt and expecting Google to read its noindex tag.
- Blocking JavaScript or CSS required to render important content.
- Copying a staging robots file into production.
- Adding broad Disallow rules without testing real URLs.
- Using robots.txt as a security boundary.
How to measure it
Measure robots.txt changes by crawl behavior, blocked URL reports, sitemap discovery, and whether important pages remain fetchable. A good robots file should reduce avoidable crawler noise without creating accidental visibility problems.
Release checklist
- Confirm the canonical URL, title, meta description, headings, and language alternates.
- Open the page on mobile and desktop to check spacing, tables, diagrams, and code blocks.
- Verify the page appears in the sitemap only when it is live.
- Check that images have useful alt text and do not create layout shift.
- Add internal links from related guides after the destination page is public.
AI review prompt
Use this prompt after you have a real URL, page draft, or crawl export. It is meant to produce fixes you can review, not automatic publishing decisions.
Act as a robots.txt reviewer.
Robots file: [paste file]
Important URLs: [list]
Private or low-value paths: [list]
Check accidental blocks, noindex misuse, sitemap host, broad patterns, and test cases for each rule.
Final review
A strong SEO page is not only optimized for a keyword. It is reachable, understandable, useful, and honest about what it can answer. Before publishing, check the rendered page, the snippet fields, internal links, indexability, and whether a reader can act without opening five more tabs.
Revisit the page when search intent changes, when the product or platform changes, when Search Console shows new query groups, or when users repeatedly need clarification. Refreshing content should make the page more accurate and useful; it should not be a cosmetic date change.